Support vector regression: epsilon, C, and a safe workflow
Support vector regression (SVR) predicts a continuous target while balancing model simplicity against errors outside an epsilon-wide tolerance. A linear kernel fits a linear function; an RBF kernel can fit nonlinear relationships.
Three settings to understand: epsilon sets the error band in target units, C controls the penalty for errors outside that band, and gamma controls the reach of an RBF kernel. None has a universally best value.
Scale features inside a pipeline, tune on training folds, and compare validation MAE or RMSE with a simple baseline. Keep the test set untouched until model selection is complete. See our cross-validation guide.
Build a sound ML workflow. Read the free Starter Kit excerpt on test sets to preview the €19 handbook. No email required.
As an extension of Support Vector Machines (SVM), Support Vector Regression has revolutionized how data scientists approach complex regression problems.
In this comprehensive guide, we’ll explore everything you need to know about SVR in machine learning, from fundamental concepts to advanced implementations.
What is Support Vector Regression?
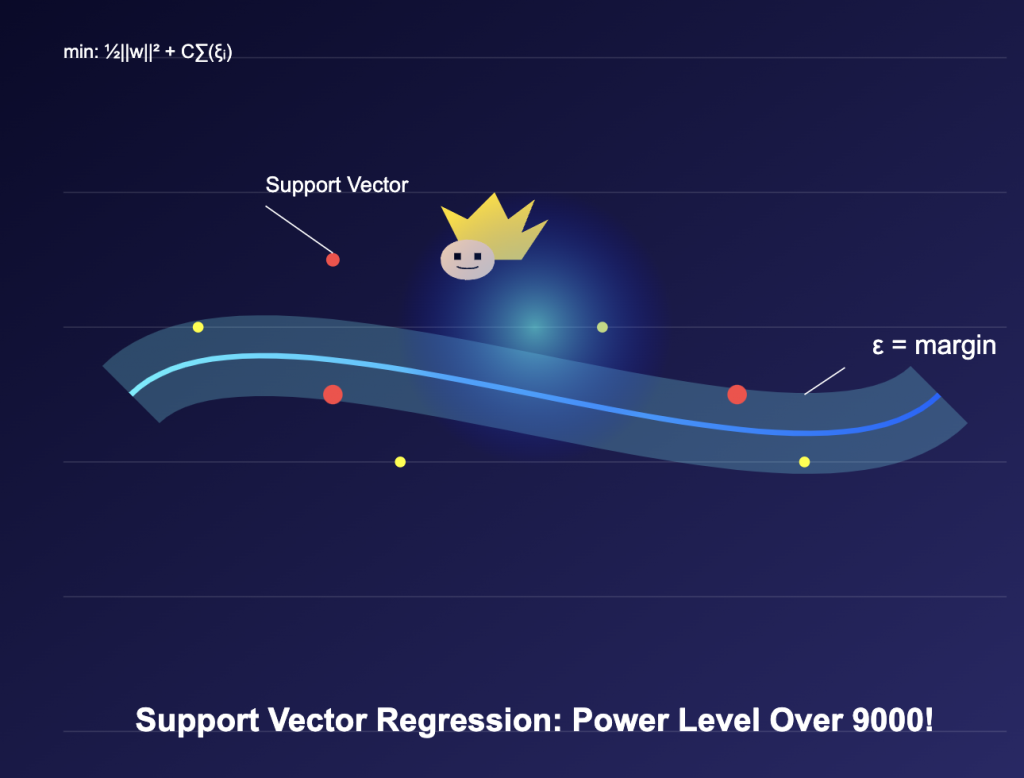
Support Vector Regression fundamentally differs from traditional regression methods by introducing an epsilon-tolerant band around the prediction line.
Unlike basic linear regression, Support Vector Regression excels at handling non-linear relationships while maintaining robust prediction capabilities, making it a standout choice for complex machine learning projects.
Core Principles of Support Vector Regression
When implementing SVR in machine learning, three fundamental components work together:
- The Epsilon (ε) Tube:
- Defines the acceptable error margin in Support Vector Regression
- Controls prediction accuracy and model complexity
- Helps optimize the SVR model’s performance
- Support Vectors:
- Key data points that define the regression function
- Determine the boundaries of the ε-tube
- Essential for SVR in machine learning applications
Epsilon example: if epsilon is 0.5 in target units, a residual of 0.3 incurs no epsilon-insensitive loss, while a residual of 0.8 contributes 0.3 before multiplication by C. Epsilon is not a hard upper bound on prediction error.
Mathematical Foundation of Support Vector Regression
The optimization problem underlying SVRs is defined as:
minimize: (1/2) ||w||² + C Σ(ξi + ξi*)
subject to:
  yi - (w·xi + b) ≤ ε + ξi
  (w·xi + b) - yi ≤ ε + ξi*
  ξi ≥ 0, ξi* ≥ 0
Key components in SVR machine learning models:
- w: Weight vector
- C: Regularization parameter
- ε: Width of the unpenalized error band
- ξi, ξi*: Slack variables
Implementing SVR in Machine Learning Projects
Setting Up Your SVR Model
from sklearn.datasets import make_regression
from sklearn.model_selection import train_test_split
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler
from sklearn.svm import SVR
from sklearn.metrics import mean_absolute_error

X, y = make_regression(n_samples=300, n_features=5, noise=10, random_state=42)
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, random_state=42
)
model = make_pipeline(StandardScaler(), SVR(C=100, epsilon=1.0))
model.fit(X_train, y_train)
print("Test MAE:", mean_absolute_error(y_test, model.predict(X_test)))
# Illustrative settings, not tuned values. Tune with CV on training data only.
Optimizing SVR Performance
When working with SVR in machine learning, these hyperparameters significantly impact model performance:
- Regularization (C):
- Controls model complexity
- Higher values: Tighter fit to training data
- Lower values: Stronger regularization; too low can underfit
- Epsilon (ε):
- Defines the SVR prediction tolerance
- Affects support vector selection
- Impacts model sparsity
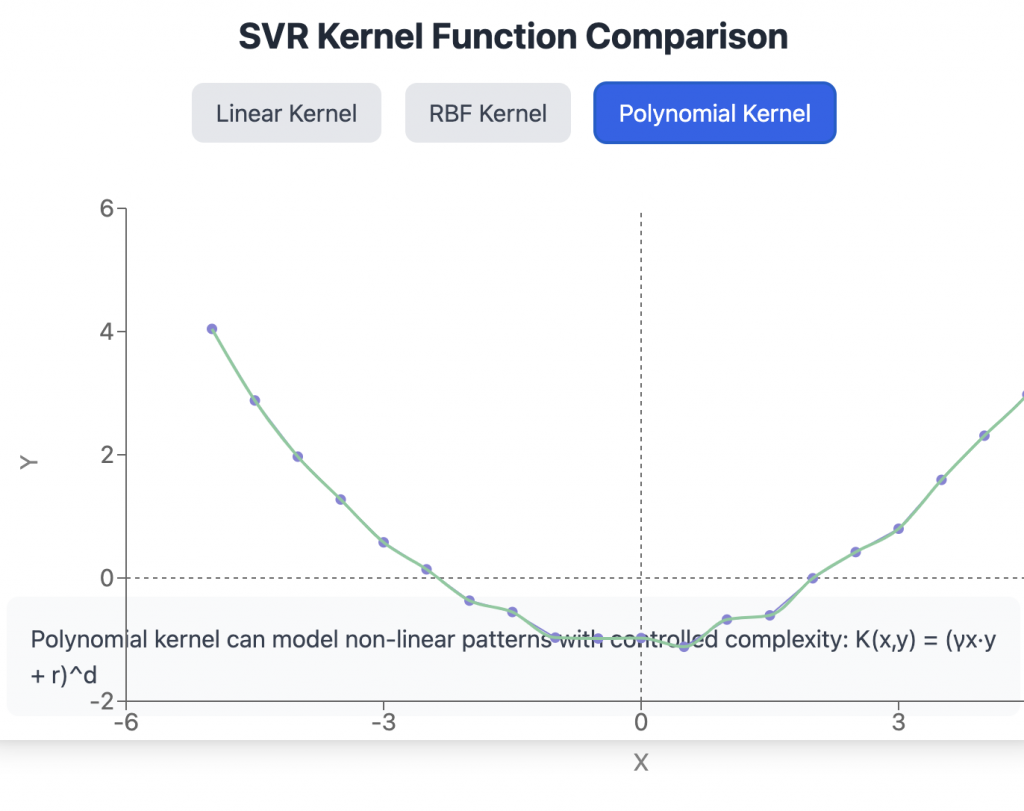
- Kernel Selection: Like SVMs, they support multiple kernels:
- Linear: For simpler relationships
- RBF: Most commonly used in SVR applications
- Polynomial: For complex nonlinear patterns
Applications of Support Vector Regression
These sort of models have proven effective in various machine learning applications:
- Financial Forecasting:
- Stock price prediction
- Market trend analysis
- Risk assessment
- Environmental Modeling:
- Climate prediction
- Pollution forecasting
- Resource optimization
- Industrial Applications:
- Quality control
- Process optimization
- Demand forecasting
Advanced SVR in Machine Learning
Handling Large-Scale Data
These models are not friend of large datasets, so when applying them to big data consider the following:
- Consider LinearSVR when a linear model is appropriate.
- For incremental fitting, consider SGDRegressor with an appropriate loss.
- Standard scikit-learn SVR does not support partial_fit; repeatedly fitting batches does not train one cumulative model.
Feature Engineering for SVR
As always, a good ol’ feature engineering can help these models get the maximum juice, so when using them consider:
- Domain-specific transformations
- Polynomial feature expansion
- Feature selection techniques
They do work well when the datasets are kind of rectangular, so wide range of features but not many examples.
Learning Resources
If you want additional support, you can master SVRs with these other AWESOME resources:
- Complete SVR Documentation on scikit-learn
- SVR Mathematical Foundations
- Machine Learning 101
- Practical SVR Implementations
- Our Guide on Online Machine Learning Courses
Summary: Mastering SVR in Machine Learning
These models stand as a cornerstone technique in modern machine learning. Its ability to handle complex nonlinear relationships while maintaining robust predictions makes it invaluable for data scientists and machine learning engineers.
By understanding their fundamentals and mastering its implementation in machine learning projects, you can tackle sophisticated prediction tasks with confidence.
Key takeaways for successful SVR implementation:
- Proper data preprocessing is crucial
- Kernel selection impacts model performance
- Hyperparameter tuning requires systematic approach
- Regular validation ensures model reliability
As always, thank you for reading How to Learn Machine Learning, and have a wonderful day!
Stay on track. Get the Roadmap.
Download the 90-Day Roadmap PDF + get weekly tips and resources to help you succeed
Subscribe to our awesome newsletter to get the best content on your journey to learn Machine Learning, including some exclusive free goodies!
