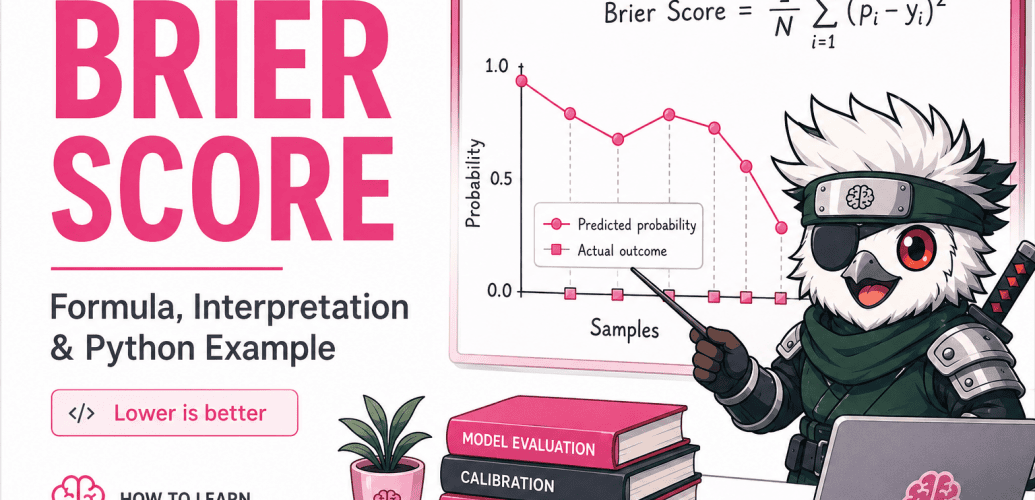
The Brier Score measures the accuracy of probabilistic predictions. A score of 0 represents perfect predictions, and lower scores are better. Unlike accuracy, it evaluates the probability assigned to an outcome, not just whether the final classification was correct.
Brier Score: Quick Reference
Binary formula: BS = (1/N) × Σ(pᵢ − yᵢ)², where pᵢ is the predicted probability of the positive class and yᵢ is its observed outcome (0 or 1). In this formulation, 0 is perfect and lower is better.
What is a good Brier score? Compare models on the same held-out data against a sensible baseline. There is no universal cutoff. A lower score alone does not prove better calibration; also inspect a reliability diagram.
Python: use brier_score_loss(y_true, y_prob) with probabilities, not class labels. See the official scikit-learn API and calibration guide for supported options.
Next step: compare probability quality with ranking performance in our Lift Curve guide, or follow the Core ML phase of the free roadmap to study evaluation in order.
Interpret a Brier score against a baseline
For two binary outcomes y = [1, 0] and predictions p = [0.8, 0.3], the Brier score is ((0.8−1)² + (0.3−0)²)/2 = 0.065. A constant 0.5 forecast scores 0.25 on these two observations. This is a tiny arithmetic example, not evidence of reliable model performance.
In a real evaluation, fit a constant-probability baseline using the training prevalence, then score it and the model on the same held-out outcomes. Record the positive class and probability convention. Differences in class prevalence can make raw scores across unrelated datasets misleading.
Use probability scores alongside precision and recall at the threshold you will actually use.
Build the habit of honest evaluation. Read the free Starter Kit excerpt on test sets. The complete practical handbook is €19.
Unlike accuracy, precision or recall, the Brier Score grades the probabilities themselves. In short:
- Brier Score = 0: perfect probabilistic predictions.
- Lower Brier Scores are better.
- For the common binary formulation, the score ranges from 0 to 1.
- It is useful when the probabilities themselves matter, not only the final predicted class.
Let’s see exactly how it works!
What Is the Brier Score?
The Brier Score is a proper scoring rule for probabilistic predictions, introduced by Glenn W. Brier in 1950.
For a binary classification problem, it is simply the mean squared difference between the predicted probability and the actual outcome.
Imagine a model predicts:
Probability of rain tomorrow = 80%
Tomorrow either:
- rains → actual outcome = 1
- doesn’t rain → actual outcome = 0
If it rains:
(0.8 - 1)² = 0.04
If it doesn’t:
(0.8 - 0)² = 0.64
The confidently wrong prediction receives a much larger penalty.
This is one of the most useful characteristics of the Brier Score: confidence matters.
Stay on track. Get the Roadmap.
Download the 90-Day Roadmap PDF + get weekly tips and resources to help you succeed
Why Should You Care About it?
In our Machine Learning journey, we often fixate on metrics like accuracy, precision, and recall. These are awesome for binary predictions, but what about when we need to quantify uncertainty? This is where our hero – the Brier Score – truly shines!
Here’s why it deserves a special place in your ML toolkit:
- It punishes overconfidence – Making bold predictions that turn out wrong? The Brier Score will call you out!
- It rewards calibration – Saying there’s a 70% chance of rain should mean it rains about 70% of the time in similar conditions.
- It’s proper – In statistics speak, this means it incentivizes honest probability assessments.
- It’s interpretable – Unlike log loss, the Brier Score has a clear upper and lower bound.
The Mathematics Behind
Let’s get a bit technical (but don’t worry, I’ll keep it friendly!).
For binary outcomes (like rain/no rain), it is calculated as:

Where:
- N is the number of predictions
- fi is your predicted probability for instance i
- oi is the actual outcome (1 if it happened, 0 if it didn’t)
If you’ve seen Mean Squared Error before, the formula should look very familiar.
For binary probabilistic predictions, the Brier Score is essentially the mean squared error between the probabilities and the outcomes.
For multi-class predictions, we use a slightly modified formula:

Where:
- C is the number of classes
- fij is the predicted probability that instance i belongs to class j
- oij is 1 if instance i belongs to class j, and 0 otherwise
A Simple Brier Score Example
Suppose we predict whether four people will buy a product:
| Customer | Predicted probability | Actual outcome |
|---|---|---|
| A | 0.9 | 1 |
| B | 0.7 | 1 |
| C | 0.4 | 0 |
| D | 0.2 | 0 |
The individual squared errors are:
- A:
(0.9 - 1)² = 0.01 - B:
(0.7 - 1)² = 0.09 - C:
(0.4 - 0)² = 0.16 - D:
(0.2 - 0)² = 0.04
So:
Brier Score = (0.01 + 0.09 + 0.16 + 0.04) / 4 = 0.075
That number by itself, however, raises an important question.
What Is a Good Brier Score?
There is no universal threshold for a “good” Brier Score.
A lower score is better, and 0 represents perfect predictions, but whether 0.10 is excellent or mediocre depends heavily on the problem.
Why?
Consider predicting a very rare event.
If an event happens only 1% of the time, a naive model that always predicts a probability of 1% can already obtain a low Brier Score. That doesn’t necessarily make it a useful model.
The better question is therefore:
Does my model achieve a better Brier Score than a sensible baseline?
A simple baseline could always predict the prevalence of the positive class.
If 20% of customers churn, for example, your baseline predicts 0.20 for every customer.
Your model should improve on that.
This is one reason you should avoid interpreting a Brier Score in isolation.
Brier Score and Calibration
The Brier Score is frequently discussed alongside probability calibration.
A model is well calibrated when its probabilities correspond to observed frequencies.
For example, among cases where a well-calibrated model predicts approximately 70% probability, the event should happen roughly 70% of the time.
But there is an important distinction:
The Brier Score is not purely a calibration metric.
It reflects several aspects of probabilistic performance together, including how well probabilities are calibrated and how effectively the model separates different outcomes.
That means a model with a lower Brier Score is not automatically better calibrated.
If calibration itself is what you want to inspect, combine the Brier Score with a calibration curve or reliability diagram. Want to try it yourself? Our probability calibration tutorial in Python walks through reliability diagrams and compares Brier score and log loss before and after calibration.
Brier Score in Python with Scikit-Learn
Scikit-learn provides brier_score_loss. For the binary examples below, pass the observed labels and a one-dimensional array of positive-class probabilities. The result is a loss: lower is better.
Which probability column? Check model.classes_ before using predict_proba. Column 1 corresponds to the second entry in that array, which is not necessarily the event you want to score. Set pos_label explicitly when needed, especially with string labels.
Why do some sources give a range of 0–2? The original multiclass definition sums squared errors across classes. The binary formula in this article uses the customary 0–1 scale. In scikit-learn 1.7 and later, scale_by_half="auto" uses 0–1 for binary classification and 0–2 for multiclass classification. Check the official brier_score_loss documentation for version-specific arguments and class ordering; compare scores only under the same convention.
import numpy as np
from sklearn.metrics import brier_score_loss

y_true = np.array([0, 1, 1, 0, 1])
y_prob = np.array([0.1, 0.8, 0.7, 0.3, 0.9])

score = brier_score_loss(y_true, y_prob)

print(f"Brier Score: {score:.3f}")
Notice that we’re passing probabilities, not predicted classes.
This is important.
Don’t do this:
model.predict(X_test)Instead, for a typical binary classifier:
y_prob = model.predict_proba(X_test)[:, 1]and then:
score = brier_score_loss(y_test, y_prob)With just a few lines of code, you can calculate the Brier Score for any classifier that outputs probabilities.
Comparing Two Models with the Brier Score
Suppose we have two classifiers:
from sklearn.metrics import brier_score_loss

model_a_prob = [0.1, 0.8, 0.7, 0.3, 0.9]
model_b_prob = [0.3, 0.6, 0.6, 0.4, 0.7]

score_a = brier_score_loss(y_true, model_a_prob)
score_b = brier_score_loss(y_true, model_b_prob)

print("Model A:", score_a)
print("Model B:", score_b)
The model with the lower Brier Score has the better overall probabilistic predictions on this dataset.
However, remember that this still doesn’t tell us why it is better.
For that, inspect complementary measures: precision and recall describe decisions at a selected threshold, while lift curves describe the concentration of positives in a top-ranked group. Use the model-evaluation checklist to choose the measure that matches your intended use.
Brier Score vs Log Loss
Brier Score and log loss both evaluate predicted probabilities, but they penalize errors differently.
The Brier Score uses a squared error.
Log loss penalizes extremely confident wrong predictions much more aggressively.
Imagine the true outcome is 1.
A prediction of 0.01 is catastrophically confident and wrong. Log loss responds very strongly to this.
The Brier Score penalizes it too, but in a bounded, quadratic way.
As a practical rule:
- Brier Score: intuitive and useful for evaluating overall probability quality.
- Log loss: particularly sensitive to confident mistakes.
It’s often useful to inspect both.
Brier Score vs ROC AUC
ROC AUC answers a different question.
AUC measures how well a classifier ranks positive observations above negative observations.
Brier Score evaluates the actual probabilities.
Imagine:
Model A: [0.51, 0.50, 0.49, 0.48]
Model B: [0.95, 0.80, 0.20, 0.05]
They could rank observations in exactly the same order and therefore have similar ranking performance, while producing very different probability estimates.
This is why AUC and Brier Score complement each other rather than replace one another.
Learn more about ranking metrics in our guide to ROC in Machine Learning.
When Should You Use the Brier Score?
The Brier Score is particularly useful when the probability itself influences a decision.
Examples include:
Weather forecasting
A 60% chance of rain communicates something fundamentally different from a 95% chance.
Medical risk
Predicting that a patient has a 5% versus 60% probability of developing a condition may lead to very different clinical decisions.
Customer churn
Businesses may prioritize interventions according to predicted churn probability.
Credit and risk modelling
Decisions often depend on estimated probabilities of default rather than a simple yes/no prediction.
Demand and event forecasting
Whenever uncertainty matters, evaluating the quality of your probability estimates becomes important.
Common Brier Score Mistakes
1. Passing classes instead of probabilities
The Brier Score is designed for probabilistic predictions. Use the probability output of your classifier.
2. Assuming a score is “good” without a baseline
A score of 0.08 can be excellent in one dataset and unimpressive in another.
Compare against a simple reference model.
3. Treating Brier Score as pure calibration
A lower Brier Score does not necessarily mean a better-calibrated model.
Use a calibration curve when calibration is your main concern.
4. Comparing scores from completely different problems
Class prevalence and problem structure influence the score, so comparisons between unrelated datasets can be misleading. Compare candidate models on the same held-out observations. If rows are time-ordered or contain repeated people or accounts, follow the cross-validation and leakage guide before interpreting an apparent improvement.
Brier Score: The Key Idea
If you remember one thing from this article, make it this:
Accuracy asks whether your prediction was right. The Brier Score asks how good the probability behind that prediction was.
For many real-world Machine Learning systems, that distinction matters enormously.
A model saying “yes” is useful.
A model saying “there’s an 82% probability” can be much more useful—provided we can trust that 82%.
That’s where metrics like the Brier Score come in.
Until next time, keep learning, keep experimenting, and keep improving those models!
Learning Machine Learning? Put This Metric in Context
The Brier Score is only one piece of model evaluation. You’ll also encounter confusion matrices, precision and recall, ROC/AUC, cross-validation, overfitting, calibration and many other concepts.
Instead of learning them randomly, follow the Free 90-Day Machine Learning Roadmap to see what to learn, in what order, and when to start building real projects.
→ Start the Free 90-Day Machine Learning Roadmap
Want to practise evaluation hands-on? Chapter 13 of the ML Starter Kit, Evaluating a Model Honestly, walks through model evaluation in Python with code that actually ran, alongside 25 other chapters that take you from setup to shipping a model.
RECOMMENDED PATH
The Fastest Way to Learn ML
Follow a structured 90-day plan to go from zero to real-world projects.
Additional Resources
Want to learn more about the Brier Score and probabilistic forecasting? Check out these excellent resources:
- Original Brier Score Paper by Glenn W. Brier
- Scikit-learn Documentation on Calibration
- Probabilistic Forecasting: A Tutorial on Kaggle
- Superforecasting: The Art and Science of Prediction book by Philip E. Tetlock
Related Articles on How to Learn Machine Learning
- ROC in Machine Learning Explained
- Partial ROC (pROC) in Machine Learning: A Practical Guide
- Lift Curve in Machine Learning Explained
- ROC Curve in Python (Code Snippet)
As always, thank you so much for reading How to Learn Machine Learning, and have a wonderful day!
Subscribe to our awesome newsletter to get the best content on your journey to learn Machine Learning, including some exclusive free goodies!
