Introduction to Boosting Machine Learning models
Boosting explained: AdaBoost versus gradient boosting
Boosting builds an ensemble sequentially: each added learner helps improve the current combined prediction. Bagging instead trains learners on resampled data without that stage-by-stage dependency.
The important distinction: AdaBoost adjusts example weights so later learners focus more on mistakes. Gradient boosting fits new learners to a loss-reduction signal; for squared-error regression, that signal is the residual.
First experiment: compare a simple baseline with shallow boosted trees using fixed validation splits. Tune learning rate and tree complexity together, and use validation-based early stopping where supported. Our model comparison guide explains when the simpler option may be enough.
Put the fundamentals into practice. Read the free Starter Kit excerpt on test sets to preview the €19 handbook. No email required.
We will avoid all the heavy maths and go for a clear, simple, but in depth explanation that can be easily understood. However, additional material and resources will be left at the end of the post, in case you want to dive further into the topic.
What is Boosting in Machine Learning?
Traditionally, building a Machine Learning application consisted on taking a single learner, like a Logistic Regressor, a Decision Tree, Support Vector Machine, or an Artificial Neural Network, feeding it data, and teaching it to perform a certain task through this data.
Then ensemble methods were born, which involve using many learners to enhance the performance of any single one of them individually. These methods can be described as techniques that use a group of weak learners (those who on average achieve only slightly better results than a random model) together, in order to create a stronger, aggregated one.
Generally, ensemble methods are built by grouping variants of individual Decision Trees, as we will see later. You can learn about decision Trees on our Tutorials section.
Boosting models fall inside this family of ensemble methods.
Boosting combines learners trained in sequence. Reweighting misclassified observations describes AdaBoost; it is not the general training rule for every boosting algorithm.
The ensemble can correct patterns that earlier stages missed, but it can still overfit, especially with noisy labels or excessive complexity. Other learners do not automatically cancel every bad prediction.
Boosting should not be confused with Bagging, which is the other main family of ensemble methods: while in bagging the weak learners are trained in parallel using randomness, in boosting the learners are trained sequentially, in order to be able to perform the task of data weighting/filtering described in the previous paragraph.
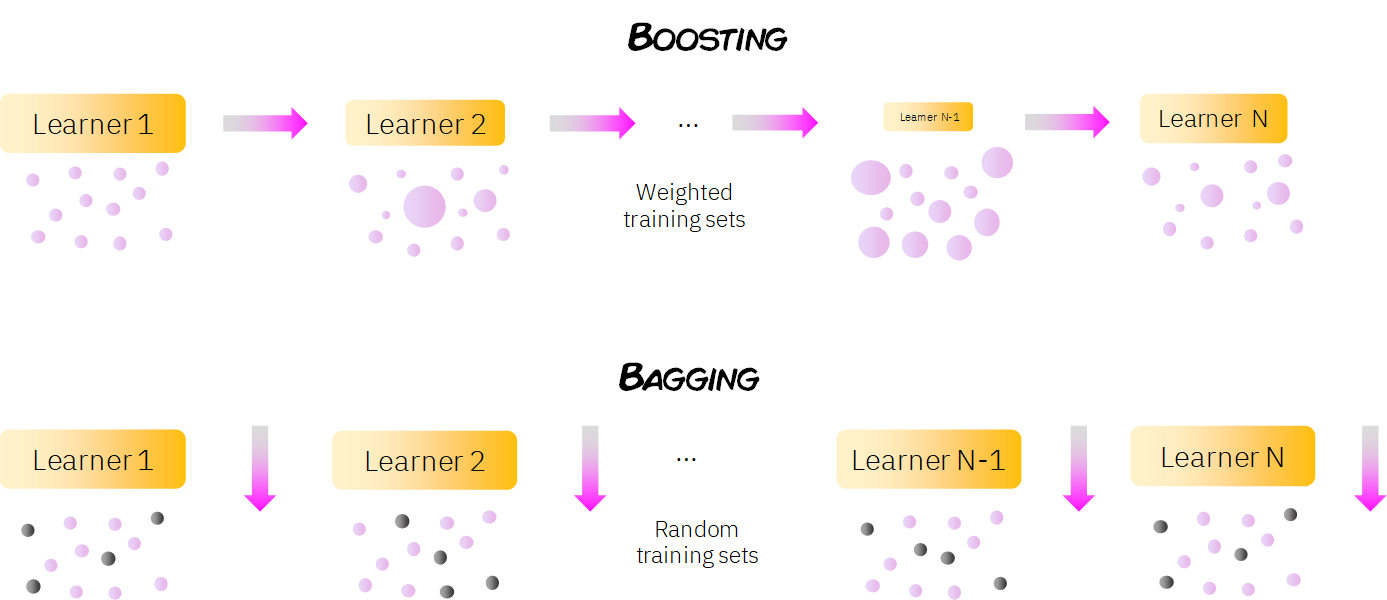
As we can see from the previous image, in boosting the models can have different importance or weights (represented in the different sizes of the learners), while in bagging all learners have the same weight in the final decision.
In AdaBoost, misclassified examples receive greater weight in the next round. Gradient boosting follows a different rule based on the chosen loss function. Bagging typically trains learners on bootstrap samples.
Now that we have seen what boosting is, and its differences with bagging, let’s see why it works so well!
Why is Boosting so effective?
Ensembling can improve predictive performance, but it does not guarantee reductions in both bias and variance. Bagging is commonly used to reduce variance; boosting builds a flexible additive model that also needs regularization.
Ensemble methods help increase the stability and performance of machine learning models by eliminating the dependency of a single estimator. This can be clearly seen with a Bagging example: Random Forest.
Random Forest are, as their name suggests, a group of individual Decision trees that make up a forest. These individual trees are quite prone to overfiting the data, and despite being very simple and intuitive models, they’re not so great at making predictions.
Averaging diverse trees can reduce prediction variance, but a random forest can still overfit or perform poorly. More trees do not fix unsuitable features, leakage, or unrepresentative training data.
In boosting, each stage depends on the ensemble built so far. AdaBoost updates sample weights; gradient boosting adds a learner that follows the negative gradient of the loss.
Also, the individual models that perform the best on the weighted training samples, will become stronger (get a higher weight), and therefore have a higher impact on the final prediction.
Alright, this sounds lovely, but how are these models actually trained?
How is a Boosting Model Trained?
The following outline describes AdaBoost-style reweighting. Gradient boosting, XGBoost, and LightGBM do not all use this same procedure:
- All the data samples start with the same weights. These samples are used to train an individual model (a Decision Tree lets say).
- The prediction error for each sample is calculated, increasing the weights of those samples which have had a greater error, to make them more important for the training of following individual model.
- Depending on how well this individual model did on its predictions, it gets assigned an importance/weight or amount of say. A model that outputs very good predictions will have a high amount of say in the final decision.
- The weighted data is passed on to the posterior model, and 2) and 3) are repeated.
- Number 4) is repeated until we have reached an certain number of models or until the error is bellow a certain threshold.

Gradient boosting fits learners to negative gradients of the loss. For squared-error regression these are ordinary residuals; other losses produce different targets. A learning rate shrinks each stage’s contribution.
We will speak about this more later, when we see the different kind of boosting models, however, the main characteristic of the family still remains: the sequential training on many individual learners to create a more powerful, aggregated model.
Awesome! Now that we know how Boosting models are trained, let’s see how they are used to make predictions on new data.
How does a Boosting Model Make Predictions?
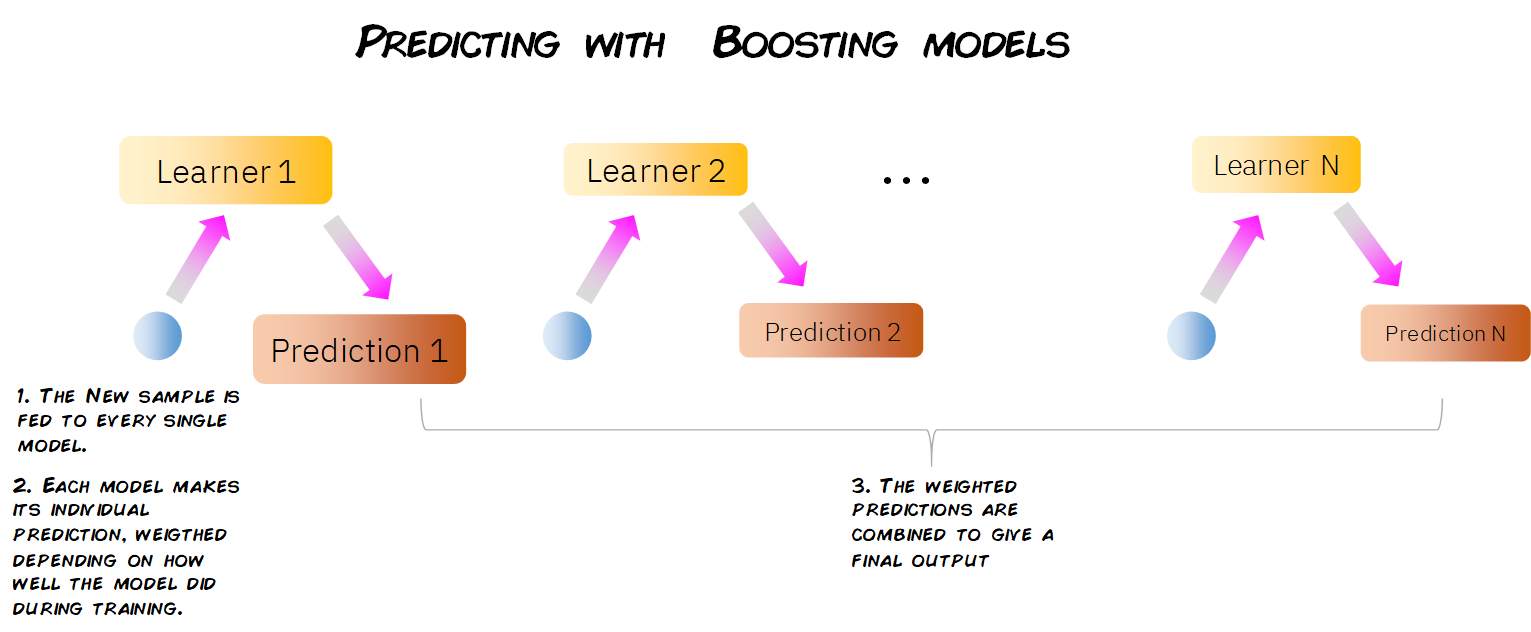
They way a boosting model makes predictions on new data is very simple. When we get a new observation with its features, it is passed through every one of the individual models, having each model make its own prediction.
Then, taking into account the weight of each one of these models, all these predictions are scaled and combined, and a final global prediction is given.
To end, lets explore the characteristics of the most common Boosting models in Machine Learning.
Different Boosting Models
Short for Adaptive Boosting, AdaBoost works by the exact process described before of training sequentially, predicting, and updating the weights of the miss-classified samples and of the corresponding weak models.
It is mostly used with Decision Tree Stumps: decision trees with just a root node and two leave nodes, where only 1 feature of the data is evaluated. As we can see, by taking into account only 1 feature of our data to make predictions, each stump is a very very weak model. However, by combining many of them, a very robust and accurate ensemble model can be built.
If you want to know more about AdaBoost, check out the following video by StatQuest.
Gradient boosting adds learners to reduce a differentiable loss. The familiar residual-fitting explanation applies directly to squared-error regression; see the scikit-learn ensemble guide for the general formulation.
The final prediction adds the contributions of successive learners, scaled by a learning rate and any stage-specific updates. Equal learning rates do not mean every tree has the same numerical effect on each prediction.
Again, if you wanna dive deeper, check out the video by StatQuest.
XGBoost implements gradient boosting with a regularized objective and efficient training methods. Its trees are decision trees fitted using loss information, rather than a fundamentally separate type of model called an XGBoost tree.
It builds these trees by calculating similarity scores between the observations that end up in a leave node. Also, XGBoost allows for regularisation, reducing the possible overfitting of our individual trees and therefore of the overall ensemble model.
Lastly, XGBoost is optimised to push the limit of the computational resources of boosted tree algorithms, making it a very high performance and fast algorithm in terms of time and computation.
You can watch the following video XGBoost Part 1: Regression, to get a deeper vision of what XGBoost is all about.
LightGBM is a gradient-boosting framework known for leaf-wise tree growth. Avoid treating this as an absolute contrast with XGBoost: XGBoost supports both depthwise and lossguide growth policies in supported tree methods. Compare runtime and validation quality under your own settings.
You can learn more about it on its official docu page.
Conclusion and further resources
Here you can find some additional resources in case you want to learn more about Boosting in Machine Learning.
- Thoughts on Hypothesis Boosting, Michael Kearns.
- A Gentle Introduction to Gradient Boosting on MachineLearningMastery.
- A Decision-Theoretic Generalization of On-Line Learning and an Application to Boosting
- QuantDare: Boosting vs Bagging
Also, in case you want to dig deeper into the topic, check out the following book reviews from our Machine Learning books section:
- The 100 Page Machine Learning book: Quick, detailed and concise book to Learn Machine learning theory.
- Hands-On Machine Learning with Scikit-Learn & TensorFlow: The perfect balance between theory and practice. Implementations and great explanations of the algorithms.
- Python Machine Learning: Very practical book for learning to implement Machine Learning algorithms.
- The Elements of Statistical Learning: Theoretical book, that was actually the first academic text to speak about Boosting Models.
Thank you very much for reading our article on Boosting in Machine Learning. We hope you enjoyed it, and learned something from it. Have a great day!
Stay on track. Get the Roadmap.
Download the 90-Day Roadmap PDF + get weekly tips and resources to help you succeed
Subscribe to our awesome newsletter to get the best content on your journey to learn Machine Learning, including some exclusive free goodies!
