Hey friends! Your first classifier worked. Now your table has numbers, text labels and missing values. How do you clean it without accidentally teaching your model something about the test set? In this scikit-learn Pipeline and ColumnTransformer tutorial, you will build one repeatable path from raw columns to predictions.
If you have not trained a model yet, start with our first machine learning project in Python. Here, basic pandas and a train/test split are enough. Open a new notebook in Google Colab and paste the code blocks into separate cells, in order.
Pipeline vs ColumnTransformer: what does each one do?
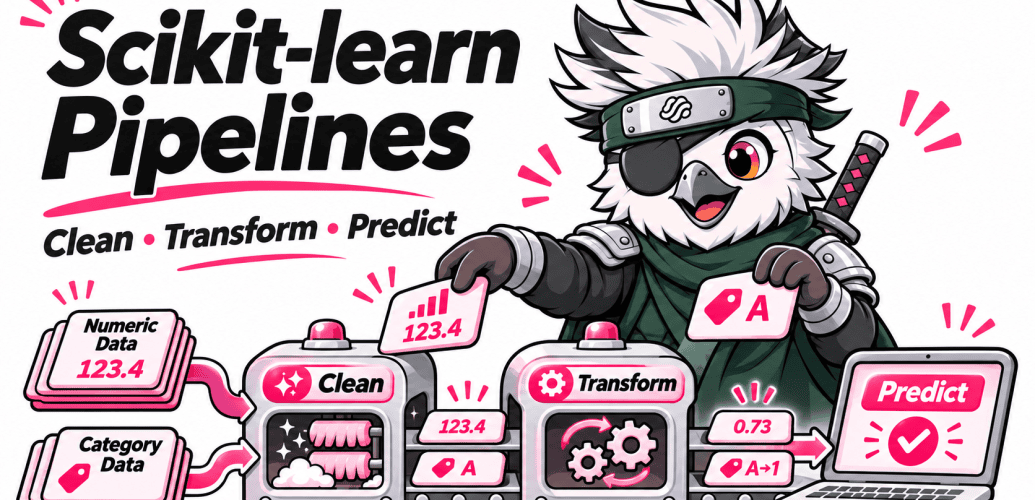
Pipeline chains steps in sequence. Our numeric branch fills missing values, then scales the columns. Our full pipeline preprocesses the inputs, then fits a classifier.
ColumnTransformer routes different columns to different transformations. Visits and minutes go through the numeric branch. Device goes through a categorical branch. Their outputs are combined into the model’s input matrix. Columns not selected are dropped by default.
Think of two questions: what should happen to each column, and in what order should those operations run? ColumnTransformer answers the first; Pipeline answers the second. Together they keep training and prediction consistent.
1. Create a small dataset with a deliberate trap
We will use 600 synthetic website visitors and predict whether they purchase. These are invented teaching data, not customer records or evidence of commercial performance. Missing minutes are injected at random; real missingness can be more complicated.
Your first mission: identify the column that would be unavailable when making the prediction. Write its name and your reasoning before continuing. Assume visits, minutes and device are measured before the purchase decision.
import numpy as np
import pandas as pd
import sklearn
from sklearn.compose import ColumnTransformer
from sklearn.impute import SimpleImputer
from sklearn.preprocessing import OneHotEncoder, StandardScaler
from sklearn.pipeline import Pipeline
from sklearn.linear_model import LogisticRegression
from sklearn.dummy import DummyClassifier
from sklearn.model_selection import train_test_split
from sklearn.metrics import accuracy_score, balanced_accuracy_score, confusion_matrix

print("scikit-learn:", sklearn.__version__)
rng = np.random.default_rng(42)
n = 600
visits = rng.integers(1, 20, n).astype(float)
minutes = rng.uniform(1, 40, n)
device = rng.choice(["mobile", "desktop"], n)
logit = -4 + 0.18 * visits + 0.08 * minutes + 0.4 * (device == "desktop")
probability = 1 / (1 + np.exp(-logit))
y = pd.Series(rng.binomial(1, probability), name="purchased")
X = pd.DataFrame({"visits": visits, "minutes": minutes, "device": device})
X.loc[rng.choice(n, 60, replace=False), "minutes"] = np.nan
# Available only AFTER purchase: deliberately unsafe as a feature.
X["receipt_sent"] = y.to_numpy()
2. Choose available features and split before fitting
A receipt is sent after a purchase. Including that information would reveal the outcome. Even a perfectly constructed pipeline cannot repair an invalid feature definition.
The assertion below catches that specific mistake. It is a teaching check, not a general leakage detector. We reserve 25% of rows for the final test and use stratification to preserve class proportions. A random split suits these independent simulated visitors; repeat visitors or chronological deployment would require a different design.
# Challenge: explain why receipt_sent must be excluded.
numeric_columns = ["visits", "minutes"]
categorical_columns = ["device"]
selected_columns = numeric_columns + categorical_columns
assert "receipt_sent" not in selected_columns, "Receipt status reveals the outcome."
X_train, X_test, y_train, y_test = train_test_split(
    X[selected_columns], y, test_size=0.25, stratify=y, random_state=42
)
Build a learning routine around the exercise. Get the Free 90-Day ML Roadmap PDF, plus weekly tips and resources by email.
3. Build the preprocessing branches
For numeric columns, median imputation supplies missing values and StandardScaler rescales the inputs. For device, most-frequent imputation handles missing entries and one-hot encoding creates category indicators. The categorical imputer is included for future missing values; this example does not inject missing device labels.
These are reasonable starting choices for this example, not universal defaults. Scaling is useful for regularized logistic regression. Median filling does not recover the true missing measurement, and adding a missingness indicator may be worth testing on validation data.
Predict before running: will the imputer learn its medians from all 600 rows, or only the training rows? The model has not been fitted yet.
numeric = Pipeline([
    ("imputer", SimpleImputer(strategy="median")),
    ("scaler", StandardScaler()),
])
categorical = Pipeline([
    ("imputer", SimpleImputer(strategy="most_frequent")),
    ("encoder", OneHotEncoder(handle_unknown="ignore")),
])
preprocessor = ColumnTransformer([
    ("numeric", numeric, numeric_columns),
    ("categorical", categorical, categorical_columns),
])
model = Pipeline([
    ("preprocess", preprocessor),
    ("classifier", LogisticRegression(max_iter=1000)),
])
4. Fit once and compare with a simple baseline
Calling fit on the full pipeline learns preprocessing from X_train and then trains logistic regression. Calling predict on X_test reuses those fitted transformations. Do not fit the preprocessor separately on the full dataset first.
This tutorial fixes the model choices in advance. If you try alternative imputers, features or regularization strengths, add validation or cross-validation within the training data. Keep the final test out of those decisions. Pass the complete pipeline into cross-validation so each fold learns its own preprocessing.
model.fit(X_train, y_train)
baseline = DummyClassifier(strategy="most_frequent").fit(X_train, y_train)
for name, estimator in [("Baseline", baseline), ("Pipeline", model)]:
    predictions = estimator.predict(X_test)
    print(name, {
        "accuracy": round(accuracy_score(y_test, predictions), 3),
        "balanced_accuracy": round(balanced_accuracy_score(y_test, predictions), 3),
    })
print("Confusion matrix: rows=true, columns=predicted, labels=[0, 1]")
print(confusion_matrix(y_test, model.predict(X_test), labels=[0, 1]))
Results from our run with scikit-learn 1.8.0: baseline accuracy 0.600 and balanced accuracy 0.500; pipeline accuracy 0.727 and balanced accuracy 0.703. The confusion matrix was [[74, 16], [25, 35]], with rows as actual labels and columns as predictions in order [0, 1].
The baseline always chooses the majority class, so its 60% accuracy hides the fact that it never identifies a purchase. Balanced accuracy averages recall across classes. The pipeline improves both measures here, but these results describe one synthetic split. They are not a promise for your dataset.
5. Challenge: an unseen device and a missing measurement
The training data contains mobile and desktop. Your next batch contains tablet. Before executing the next cell, answer: will prediction fail? How will the missing minutes value be filled? Does successfully returning a probability mean the model understands tablet visitors?
# Predict BEFORE running: will an unseen category cause an error?
new_visitors = pd.DataFrame({
    "visits": [4.0, 12.0],
    "minutes": [np.nan, 25.0],
    "device": ["tablet", "mobile"],
})
print("Purchase probabilities:", model.predict_proba(new_visitors)[:, 1].round(3))
fitted_numeric = model.named_steps["preprocess"].named_transformers_["numeric"]
print("Training medians:", fitted_numeric.named_steps["imputer"].statistics_)
print("Training-column medians:", X_train[numeric_columns].median().to_numpy())
assert np.allclose(
    fitted_numeric.named_steps["imputer"].statistics_,
    X_train[numeric_columns].median().to_numpy()
)
In our run the two predicted probabilities were approximately 0.160 and 0.476. The final assertion checks that the stored numeric imputation values equal the training-column medians. It verifies this preprocessing detail; it does not prove the entire dataset is free of leakage.
Common mistakes to catch before you trust the result
Fitting twice: calling fit_transform on both training and test data gives them independently learned preprocessing. Fit on training data and transform later data using the fitted object.
Cleaning before splitting: learning medians or scaling statistics from the full dataset lets test information influence training. Keep learned transformations within the pipeline.
Using unavailable columns: a payment confirmation, final diagnosis or future total can encode the answer. Define the prediction time before selecting features.
Tuning against the test score: changing settings after inspecting the test set turns it into a development tool. Use a separate validation strategy. See our model evaluation guide for the next steps.
Ignoring the input contract: new data still needs the expected columns and compatible types. Unknown-category handling does not make arbitrary schemas safe. A completely missing column is different from a missing value inside an existing column.
Answers and explanations
Mission 1: exclude receipt_sent. It is defined from the target and becomes available after the event. The problem is when information becomes available, not merely whether its correlation is high.
Mission 2: the numeric imputer learns from the training rows only because fit receives X_train. The fitted statistics were approximately [10.0, 20.7844] for visits and minutes in our run.
Mission 3: tablet does not cause an encoding error because handle_unknown=’ignore’ represents it with zeros across the learned device-category indicators. This is a fallback representation, not a newly learned tablet category. Monitor unseen categories and decide when retraining is appropriate.
Mission 4: missing minutes uses the stored training median, then the stored scaler transforms it. The prediction remains possible, but missing inputs and unfamiliar populations can reduce reliability.
Bonus challenge: write down why a pipeline cannot fix a train/test split that mixes future observations into training. Answer: the pipeline controls where transformations are fitted; it does not choose an appropriate temporal or group split for you.
Turn the exercise into something you can explain
Choose a different small dataset, define when predictions would be made, and document which columns are available then. Compare with a baseline, describe one preprocessing decision and include a limitation. Use our portfolio README template to structure the explanation. Credit this tutorial and distinguish your changes from the starting example.
Want a guided companion for the broader workflow? Explore the ML Starter Kit. Keep practising, friends: a model you can explain and reproduce is a much better learning outcome than a score you cannot defend.
References
scikit-learn: ColumnTransformer with mixed types and common pitfalls and recommended practices. The synthetic exercise and reported results above were created and executed for this tutorial.
Subscribe to our awesome newsletter to get the best content on your journey to learn Machine Learning, including some exclusive free goodies!
